Case study
Medical Image Classifier API
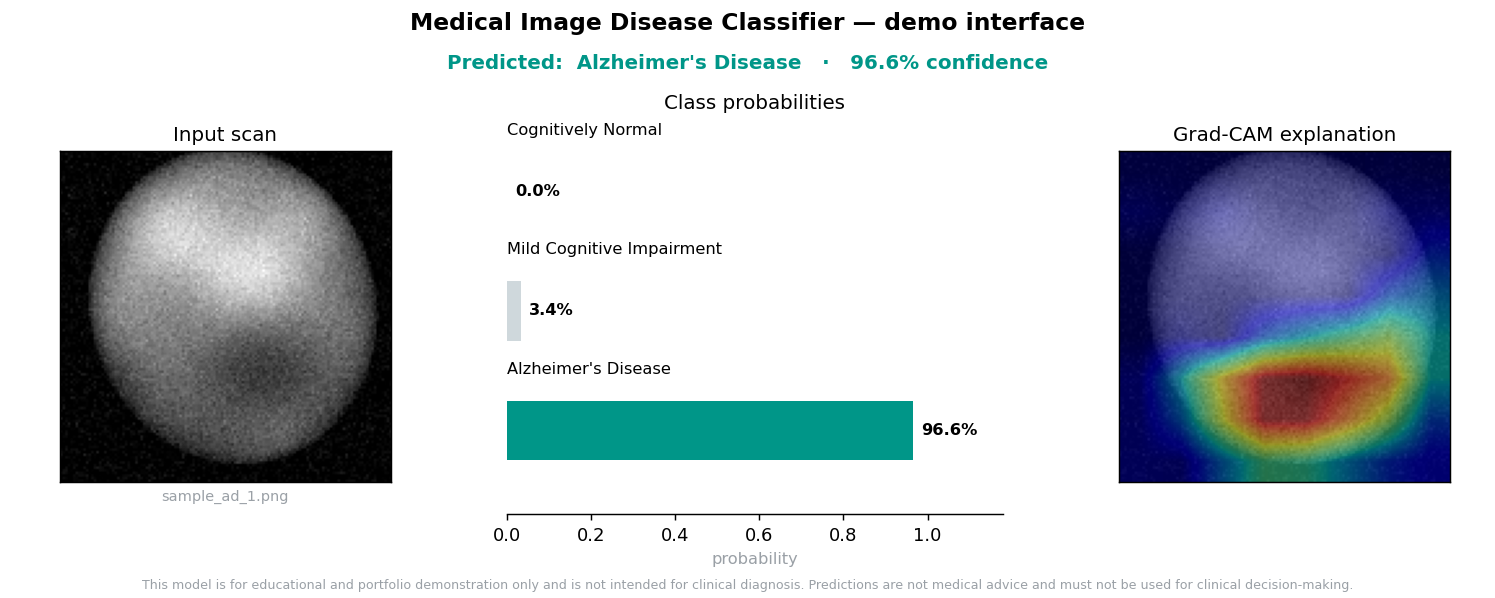
I built an image classification service with PyTorch and FastAPI that returns a prediction, a score for each class and a Grad-CAM heatmap. It is trained on synthetic brain-phantom images and is not for clinical use.
- PyTorch
- FastAPI
- Medical Imaging
- Grad-CAM
- Docker
- CI
- synthetic test images classified correctly (94%)
- 127/135
- macro-F1 on the same synthetic test split
- 0.94
- automated tests, run in CI
- 20
- model parameters in a 0.4 MB checkpoint
- 97,779
Demo only, not a diagnostic tool. The model is trained and tested on procedurally generated images, not real scans, because the scans from the original project (ADNI PET) are access-restricted. The numbers show that the pipeline works. They say nothing about clinical accuracy.
How it works
Generate data
A seeded generator draws grayscale brain-phantom images in three classes that differ by how much one region is dimmed. The default set is 810 images.
Preprocess
Grayscale, resize to 128 by 128, percentile scaling, then standardization. Training and serving call the same function.
Train
A small CNN with four convolution blocks trains on CPU with Adam and early stopping on validation loss.
Package
The checkpoint stores the weights together with the class order and the normalization statistics, so the server reads them from the file.
Predict
FastAPI checks each upload, then POST /predict returns the predicted class, a confidence score and a score for every class.
Explain
A separate POST /explain call returns a Grad-CAM overlay as a PNG, showing which region drove the prediction.
 Opens the full-size picture in a new tab.
 Opens the full-size picture in a new tab.
The problem
This project grew out of an earlier Alzheimer's PET classification project (also on this site) that trained transfer-learning models and stopped at the notebook stage. It does not reuse that data or those models. It builds the part the notebook lacked: a service someone else can run.
The real scans (ADNI) are access-restricted and cannot be redistributed, so the repo generates its own data. The three classes carry the names Cognitively Normal, Mild Cognitive Impairment and Alzheimer's Disease. In this data they differ only by how much one region of the image is dimmed.
What I built
A small PyTorch CNN with a FastAPI service around it. The part I cared about most is consistency between training and serving. Both call the same preprocessing function, and the normalization statistics and class order travel inside the checkpoint, so the server never hard-codes them.
- POST /predict returns the predicted class, a confidence score, a score for each of the three classes and a disclaimer.
- POST /explain returns a Grad-CAM overlay as a PNG. Grad-CAM is implemented with PyTorch hooks, without an external library.
- Bad uploads are rejected before inference: wrong type (415), empty file (400), over 10 MB (413) or not a readable image (422).
- The API, a command-line script and a Streamlit demo all go through the same Predictor class.
Results
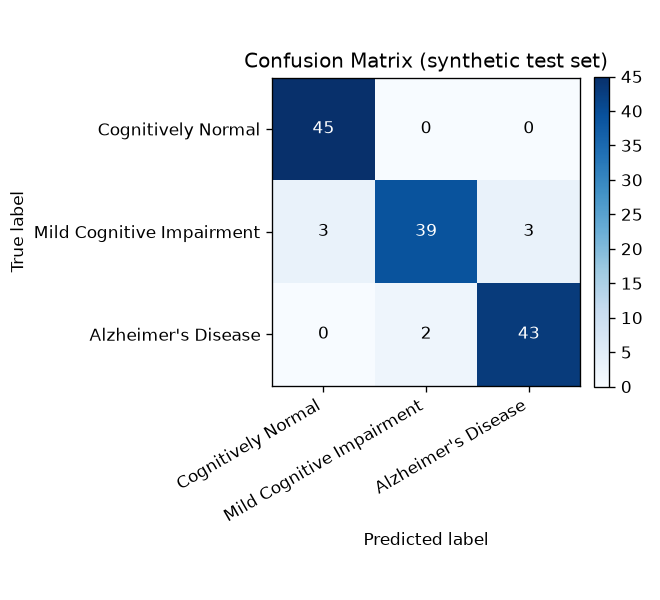
On the held-out synthetic test split (135 images from the same generator, never used in training) the committed model gets 127 right. That is 94% accuracy and a macro-F1 of 0.94, from a single training run with a fixed seed.
Mild Cognitive Impairment, the middle class, is the hardest, with a recall of 0.87. All 8 errors are between neighboring classes. That is expected, because the generator separates the classes along one dimming factor with random jitter that makes neighbors overlap.
These are generated shapes, not real scans. The numbers show that the pipeline works end to end and say nothing about clinical performance.
Testing and delivery
20 pytest tests cover the API, preprocessing, the model and checkpoint, and the predictor with Grad-CAM. The API and predictor tests run against a small untrained checkpoint, so the suite checks shapes, response contracts and error handling, not accuracy. The training and evaluation code is not covered by tests.
GitHub Actions runs Ruff and pytest on Python 3.10 and 3.11 on every push to main and on pull requests, and a second job builds the Docker image. The image runs as a non-root user and has a health check.
Limits and next steps
- Not a diagnostic tool. The model is not clinically validated.
- Trained on synthetic data, so the metrics will not transfer to real scans.
- The 94% figure comes from one training run on 135 test images, and CI does not re-run training.
- Softmax scores are not calibrated probabilities.
- Nothing here handles differences between scanners, sites or populations.
- Not built yet: transfer-learning backbones, cloud deployment, authentication and rate limiting.
Built with
- Model
- PyTorch
- Custom CNN
- Grad-CAM
- Data and evaluation
- NumPy
- Pillow
- scikit-learn
- Matplotlib
- API and demo
- FastAPI
- Pydantic
- Uvicorn
- Streamlit
- Tooling
- pytest
- Ruff
- GitHub Actions
- Docker